SAN FRANCISCO, July 23, 2026 (GLOBE NEWSWIRE) -- Timed with AMD Advancing AI 2026, Embedded LLM, an agentic inference infrastructure company in the AMD Instinct™ AI & HPC Software Ecosystem and a Red Hat ecosystem partner, today launched TokenVisor Spaces for AMD-powered AI clouds and enterprises.
The announcement aligns to the event's focus on AI infrastructure, enterprise deployment, developers, customers, and partners: TokenVisor Spaces is designed to help AI cloud operators turn AMD-powered systems into governed agentic AI services.
The business case is simple: agents do not only generate tokens. They need somewhere to run tools, browsers, code, files, queues, approvals, and enterprise workflows - and that work runs where enterprise software already lives: x86-64. They need policy, metering, and audit before enterprises will put them in production. And they need fast, governed access back to model inference.
TokenVisor Spaces provides exactly that on AMD server infrastructure: agent execution on AMD EPYC™ x86 CPUs, model inference on AMD Instinct GPUs, policy and metering through TokenVisor, and replayable workspaces that enterprises can audit and operate. For AI clouds, it is a way to sell more than raw GPU hours: governed agent services. For enterprises, it allows agents to work with existing applications inside isolated containers on infrastructure they control.
“The next AI cloud product is not a GPU hour. It is a governed agent service,” said Ghee Leng Ooi, CEO of Embedded LLM. “TokenVisor Spaces turns AMD-powered infrastructure into a place where agents can actually work: execute tools, persist state, follow policy, leave traces, and connect back to high-performance inference. Agentic AI runs where enterprise software runs, and that makes the CPU plus GPU platform the center of the next AI cloud.”
Partner Deployment Path
Validated on Red Hat OpenShift, TokenVisor Spaces gives enterprises isolated agent sandboxes with governed LLM access. OpenShift manages containers and GPUs; TokenVisor enforces entitlements, routing, budgets, rate limits, metering, and auditability. Embedded LLM is listed in the Red Hat Ecosystem Catalog.
“Agentic AI requires a balanced compute platform that brings CPU-based execution and GPU-accelerated inference together,” said Dan McNamara, senior vice president and general manager, Compute and Enterprise AI, AMD. “By combining AMD EPYC processors and AMD Instinct accelerators, TokenVisor Spaces shows how ecosystem software can help cloud providers and enterprises deploy open, governed agent services on infrastructure they control.”
“Modern AI infrastructure needs a balanced CPU plus GPU platform. AMD EPYC processors provide host-node performance, memory bandwidth, high-performance I/O, efficiency, and GPU ecosystem compatibility for GPU-accelerated AI systems, while AMD Instinct GPUs deliver the acceleration needed for large-scale inference. Embedded LLM's TokenVisor Spaces show how ecosystem software can bring these two planes together for production agentic AI on AMD-powered infrastructure.”
What TokenVisor Spaces Provides
TokenVisor Spaces gives each agent a controlled workspace on customer-managed infrastructure. Each capability answers something agents need that raw infrastructure does not provide:
- Agents run for days, not single requests. Spaces provides persistent x86-64 workspaces for long-running, multi-turn agents.
- Agents execute real code against real systems. Spaces provides isolated execution for shell, files, code, browser automation, and tools.
- Agents take actions enterprises cannot let run unattended. Spaces provides human approval workflows for sensitive actions.
- Agents fail in ways someone must be able to reconstruct. Spaces provides replayable event history for review, debugging, audit, and evaluation.
- Agents consume models continuously. Spaces provides governed model access through TokenVisor, including agent guardrails, policy, metering, routing, and usage controls.
Agentic inference is making data movement part of the performance path.
Long-context agents need their accumulated context back on every turn without paying full prefill each time. The market evidence is already public: SemiAnalysis reported that across 1.5M+ of its own Claude Code requests, roughly 95% of all tokens were cache reads, cutting its prompt-token bill by about 84%. Agentic inference economics are cache economics - and the cache has to live somewhere with more capacity than GPU HBM.
Embedded LLM has validated the model-plane data path for exactly this on AMD Instinct MI355X. In a production-shaped synthetic agentic replay, storage-backed KV-cache reuse using vLLM, a KV-cache management layer, AMD hipFile/GDS, and native local NVMe delivered 3.31x lower warm-turn median latency and 2.23x faster total wall-clock time versus a matched vLLM HBM prefix-cache baseline.*
Embedded LLM is collaborating with VAST Data and Tensormesh for platform-scale KV-cache reuse, agent state, trace capture, replay/evaluation, and RL data.
“KV-cache reuse is what makes long-running, multi-turn agents economically viable,” said Kuntai Du, Chief Scientist and Co-founder at Tensormesh. “By adopting LMCache, Embedded LLM brings that infrastructure to more of the AI cloud market, giving agents persistent, reusable context so they run faster, are more cost-effective, save energy and stay auditable at scale.”
“Agentic AI requires infrastructure that can efficiently manage context, data, and state across long-running AI workflows,” said Anat Heilper, Director of AI Architecture at VAST Data. “Our collaboration with Embedded LLM helps bring the VAST AI Operating System to AMD-powered AI environments, giving customers the persistent data foundation they need to scale production AI with greater performance and efficiency.”
Availability
TokenVisor Spaces is available for partner deployment and evaluation by AI cloud operators, private AI environments, and on-premises enterprises. Prospective customers can request a demo, start a trial, join an evaluation program, or arrange a proof of concept through the Embedded LLM contact form or by emailing info@embeddedllm.com. Product information is available at embeddedllm.com.
About Embedded LLM
Embedded LLM is an agentic inference infrastructure company in the AMD Instinct AI & HPC Software Ecosystem and a Red Hat ecosystem partner. The company helps AI clouds and enterprises turn GPU fleets into production AI services through vLLM-based serving, TokenVisor for governed model APIs and monetization, TokenVisor Spaces for stateful agent execution, JamAI Base for traceable AI operations, and operator-level RL/post-training infrastructure.
Media contact:
Lim Jia Qi
pr@embeddedllm.com
https://embeddedllm.com/
AMD, the AMD arrow logo, EPYC, Instinct and combinations thereof are trademarks of Advanced Micro Devices, Inc.
Technical Appendix
- Validation scope: TokenVisor Spaces deployment validation was completed on the Supermicro AS-8126GS-TNMR with AMD Instinct MI350X GPUs and dual AMD EPYC 9575F processors. The KV-cache performance results below are a separate model-plane benchmark conducted on AMD Instinct MI355X GPUs with native local NVMe.
- Benchmark scope: results measured by Embedded LLM on AMD Instinct MI355X GPUs with AMD hipFile/GDS and native local NVMe storage, using vLLM, LMCache ConnectorV1, 24 independent long-context session families, five turns per family, concurrency two, 500-token controlled outputs, Qwen3-235B-A22B-Instruct-2507-FP8, and a matched GPU-HBM prefix-cache baseline.
Detailed MI355X result:
- 3.31x lower warm-turn median latency.
- 3.33x lower warm-turn p90 latency.
- 3.32x higher warm request rate.
- 2.23x faster total wall-clock time.
- Full cache retrievals and zero fallback I/O observed.
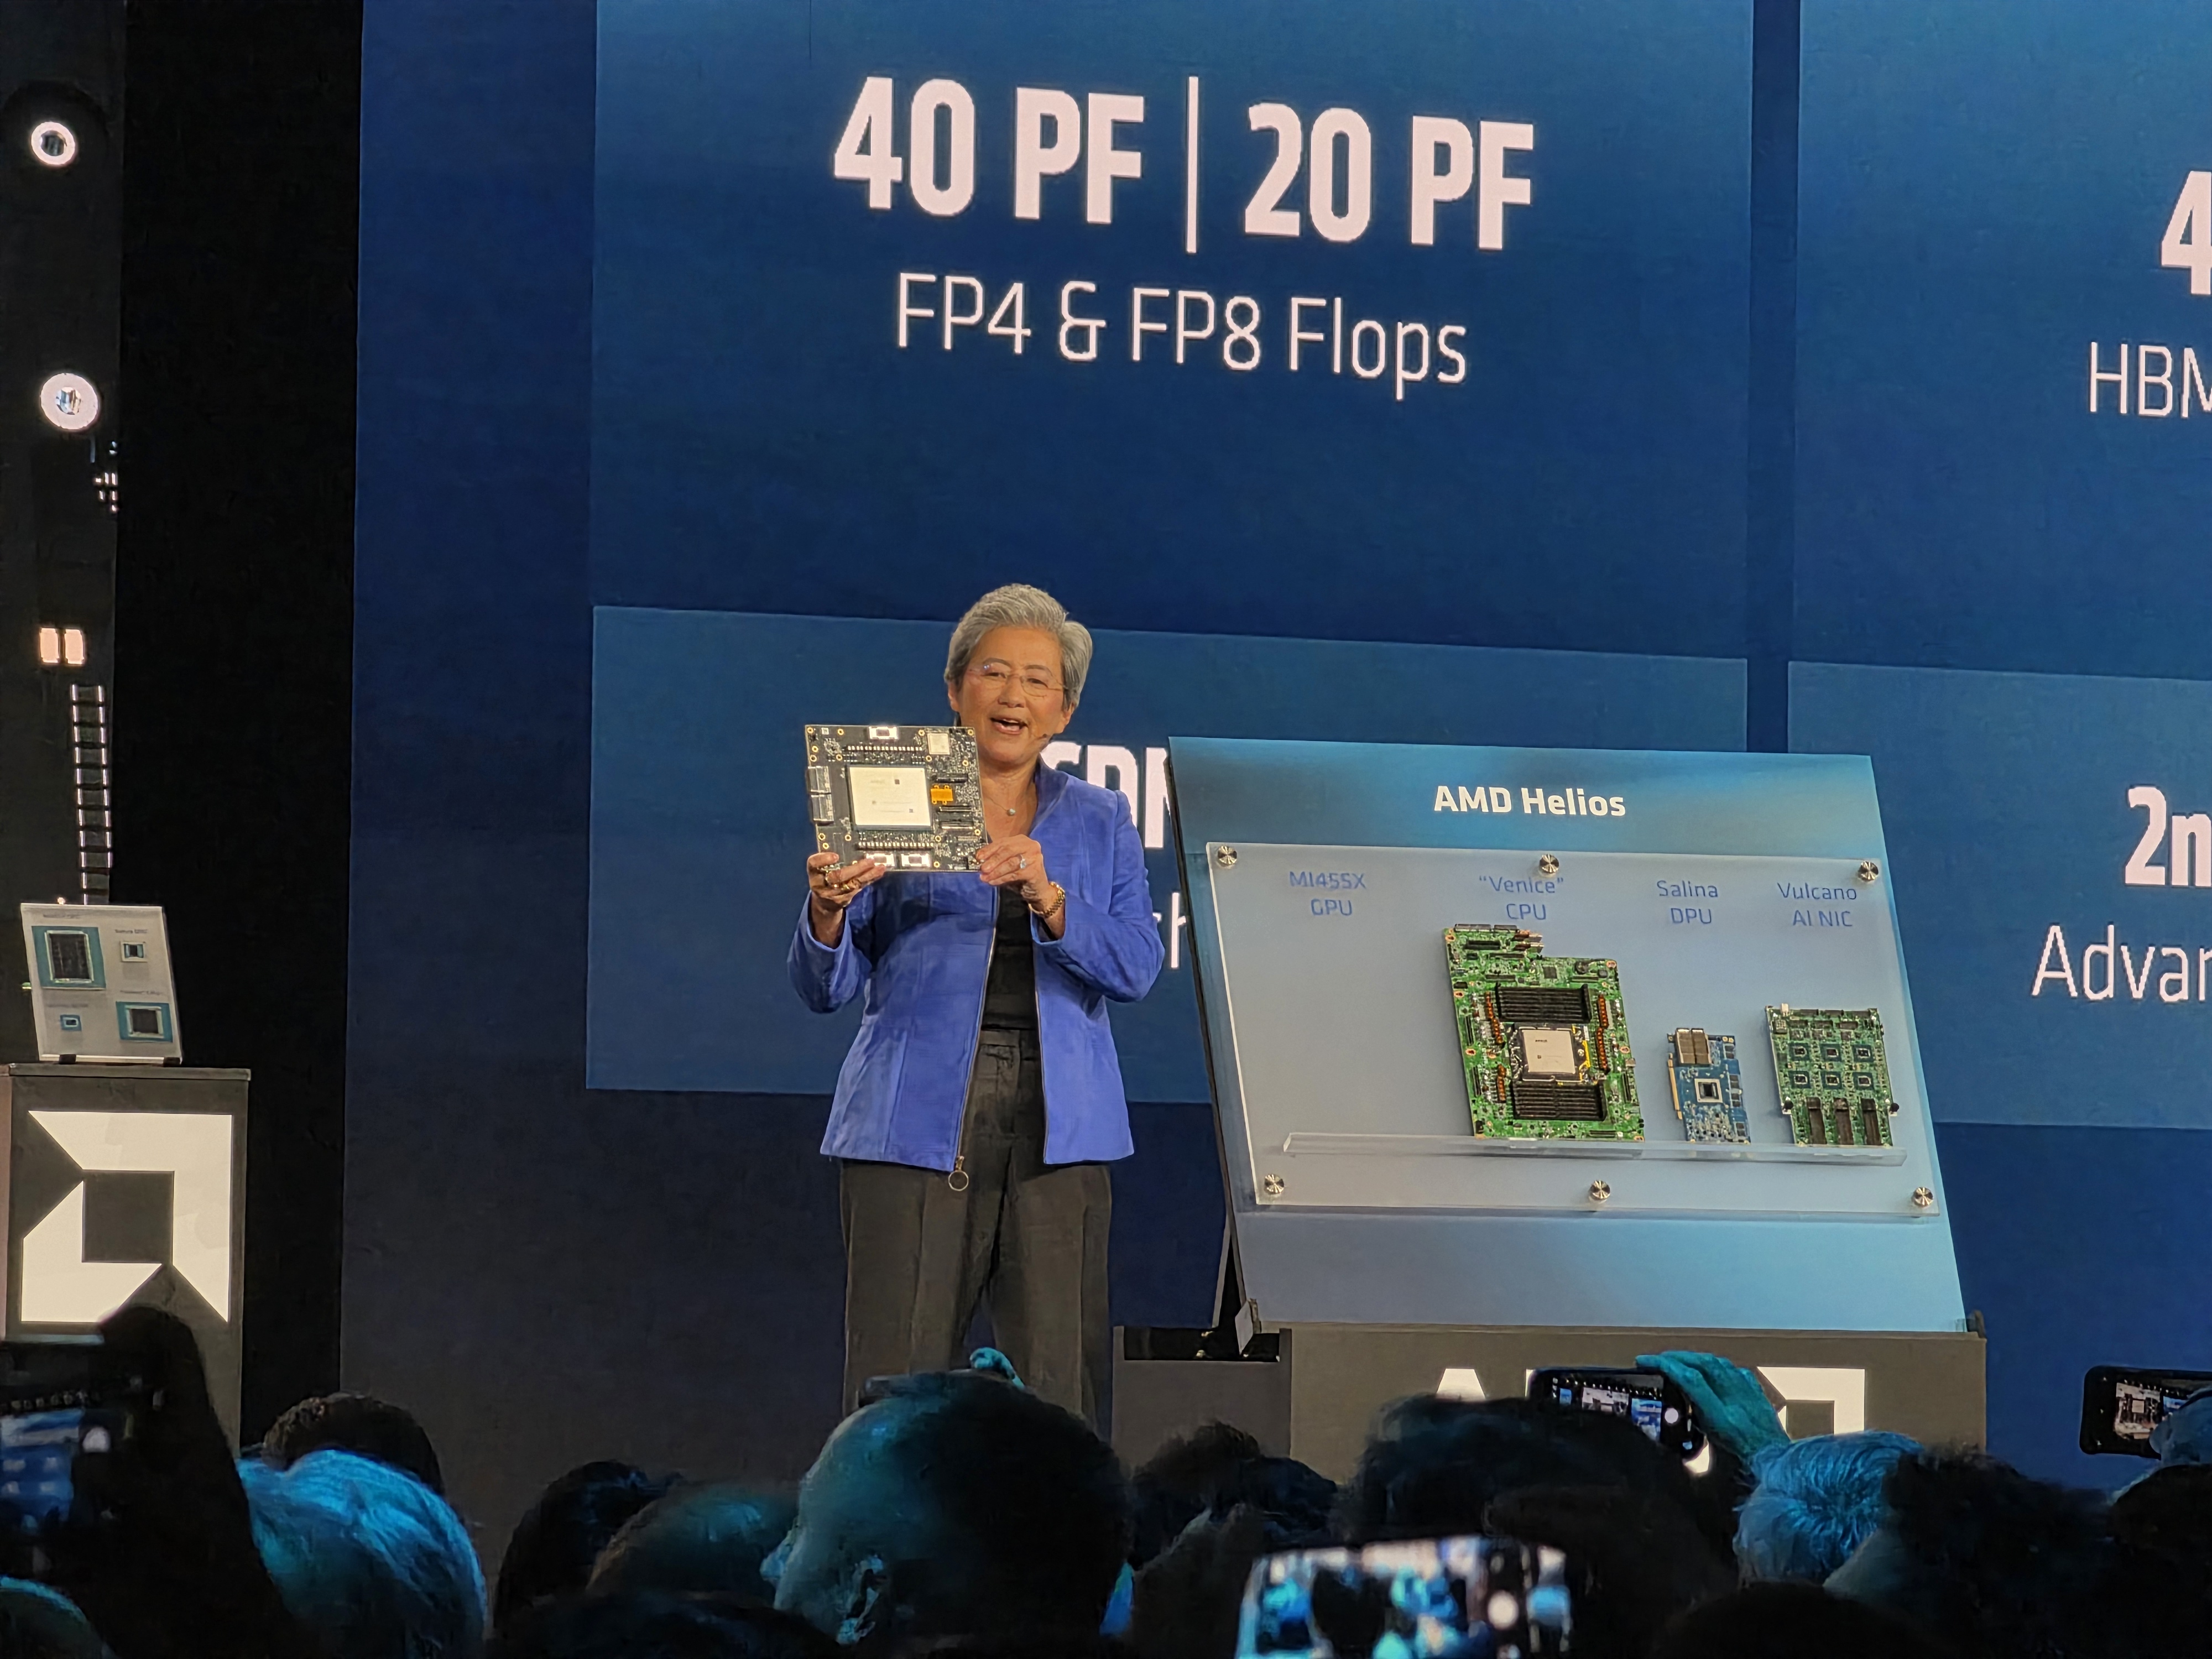
A photo accompanying this announcement is available at https://www.globenewswire.com/NewsRoom/AttachmentNg/31b6f0c4-2977-4ab6-84ff-68eee38da222